All articles

Cost Optimization

7 articles

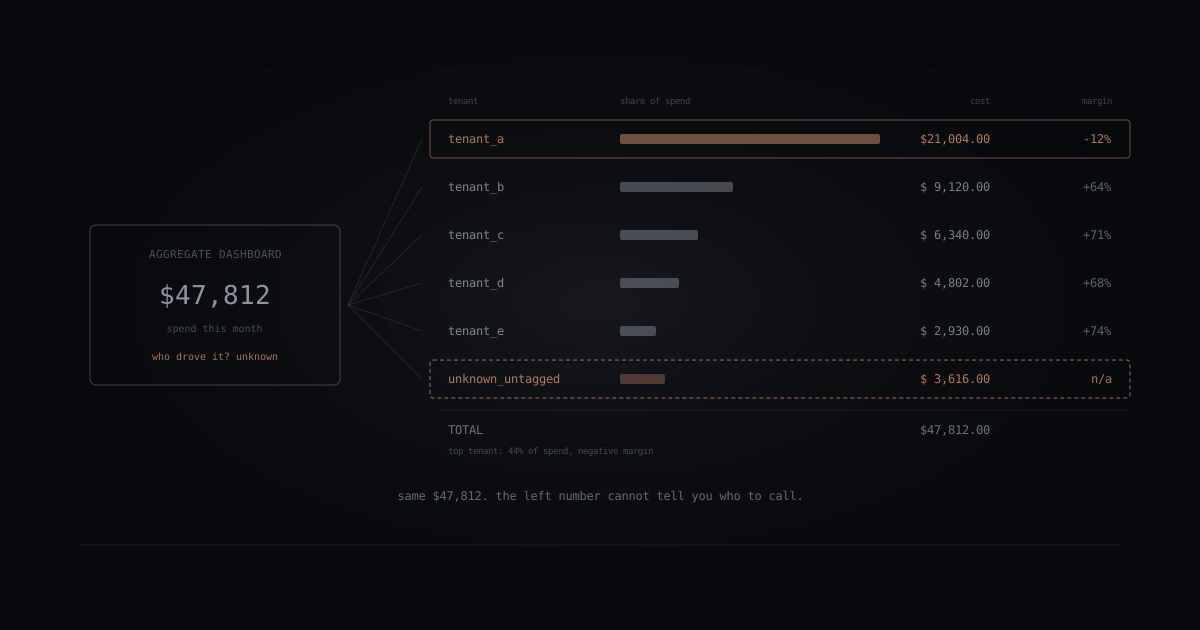
A single aggregate spend figure fanning out into a six row per tenant cost ledger where one tenant consumes 44 percent of spend at negative margin and an untagged unknown bucket is flagged in orange.

Per-tenant AI cost attribution: why aggregate dashboards are not enough

Aggregate AI spend hides who is driving cost. Per-tenant attribution shows who to charge, who is profitable, and where margins leak.
Cost OptimizationProduction AIPlatform DevelopmentAI Architecture
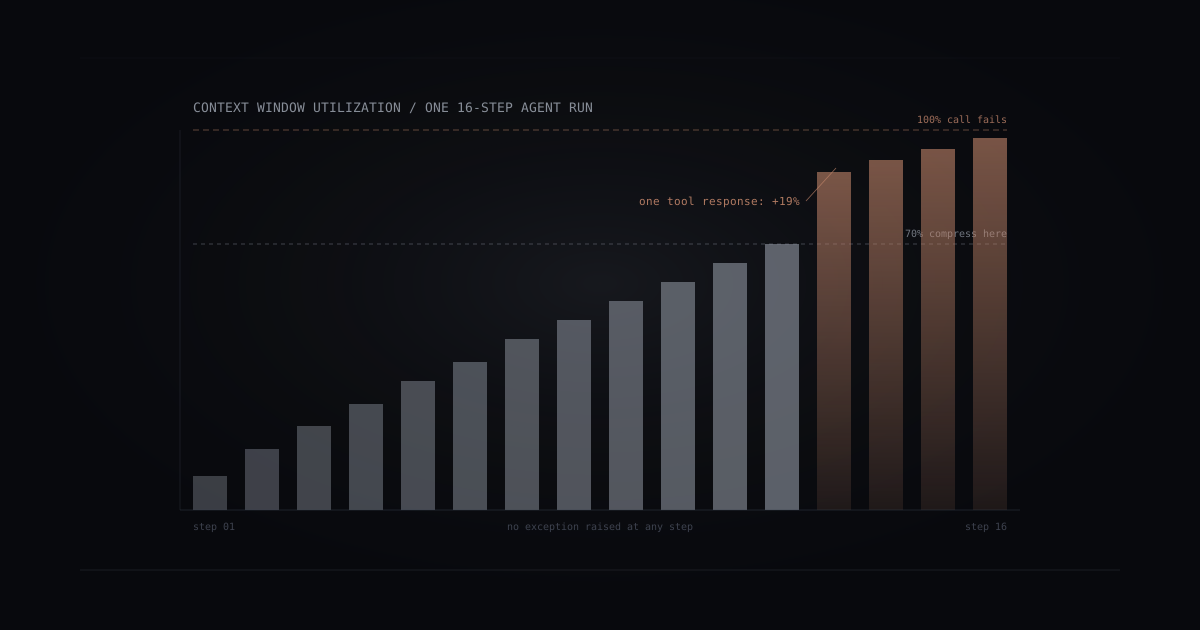
A bar chart of context window utilization across a sixteen step agent run, where the final four bars in warm orange break past the seventy percent compression threshold and press against the hard ceiling.

The token budget problem: why your production agents run out of room

Context windows are finite. Production workloads are not. Here is what actually breaks when an agent exhausts its budget, and three patterns that prevent it.
AI EngineeringProduction AICost OptimizationMulti-Agent Systems
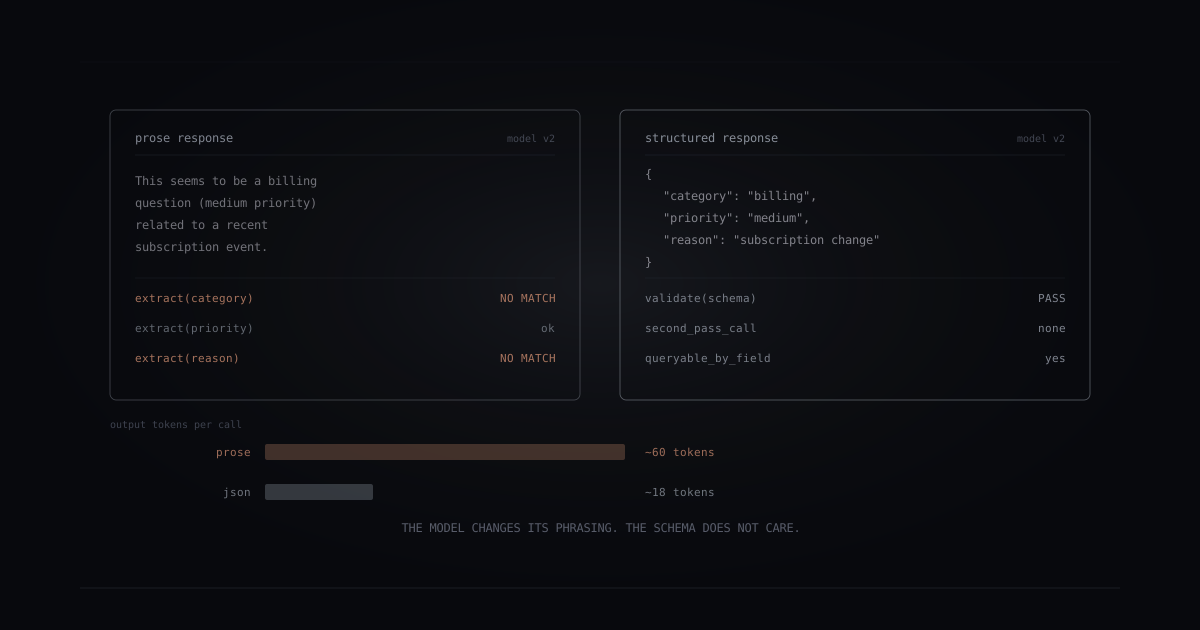
A side by side comparison panel showing a prose model response with two failed extraction rows next to a validated JSON object, with token bars measuring sixty tokens against eighteen.

The case for structured outputs in production AI

Most production AI systems parse prose from LLMs instead of requesting structured JSON, and the cost and reliability gap this creates is larger than expected.

AI EngineeringProduction AICost OptimizationSoftware Architecture
Stylized invoice with seven highlighted line items: input/output tokens, model mix, cache discount, batch, embeddings, retries, and egress

Reading an LLM bill: line items that actually matter

Most LLM bills get scanned for total cost. Seven line items carry the real signal. A 5-minute monthly review that turns the bill into a diagnostic.
Cost OptimizationAI Operations
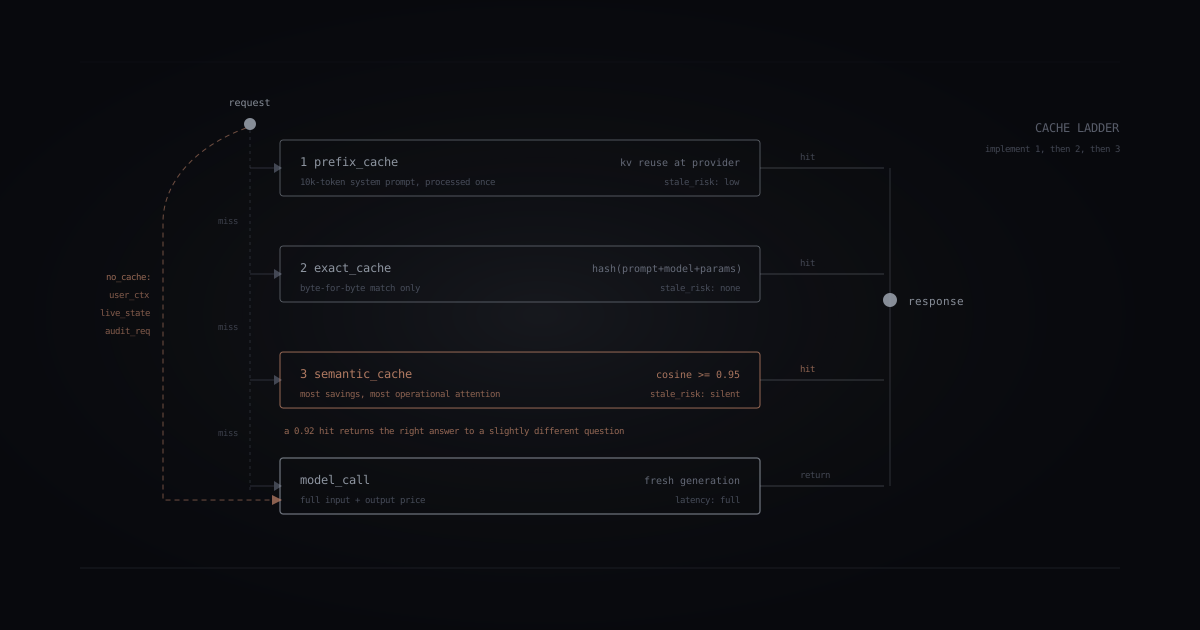
Cache waterfall diagram with three stacked layers labeled prefix cache, exact cache, and semantic cache, each showing a stale risk readout, plus a dashed bypass lane routing user context and live state directly to the model call.

Caching strategies for LLM applications

LLM responses are expensive, slow, and often repeated. Here is how to cache them without building a system that silently returns stale answers.

LLMCost Optimization
Descending cost curve with glowing data points showing AI cost optimization over time

Why Your AI Gets More Expensive Over Time (And How to Reverse It)

Three months after launch, one company's AI bill tripled. Distillation, prompt compression, and model routing can cut inference costs 50-80%.

Cost OptimizationAI Operations
Cost breakdown visualization showing the four categories of AI implementation spend

AI Implementation Costs in 2026: What Companies Actually Spend

A weekend AI prototype cost $47. The production version cost $180,000. Here is what companies actually spend, and where they overspend.

Cost OptimizationAI Strategy