The AI skills gap is not what you think it is
The real AI shortage is not ML engineers. It is domain experts who can evaluate AI outputs, and organizations that know what they want before they start hiring.
What AI systems need from product managers
Traditional PM frameworks miss AI feature requirements, producing poorly specified features, misaligned success metrics, and avoidable production failures.
Prompt engineering is not a substitute for system design
Prompt engineering is a real skill. It is also the most misused tool in AI development: applied to problems that require system redesign, not better prompts.
How to measure AI feature success
AI features fail in ways standard product metrics miss: users can be unhappy without errors rising. Measuring AI success needs different instrumentation.
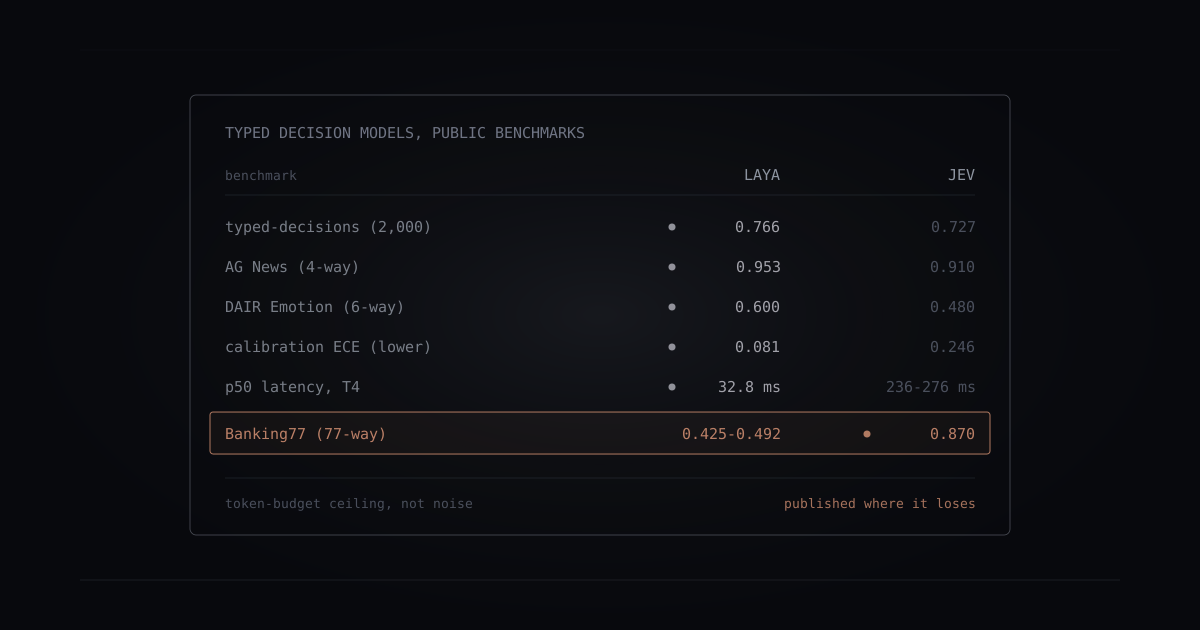
Laya vs Jev: an open-source benchmark of typed decision models
We benchmarked open-source Laya against TypeSafe's Jev on public datasets and internal scenarios: accuracy, latency, calibration, and where each wins.
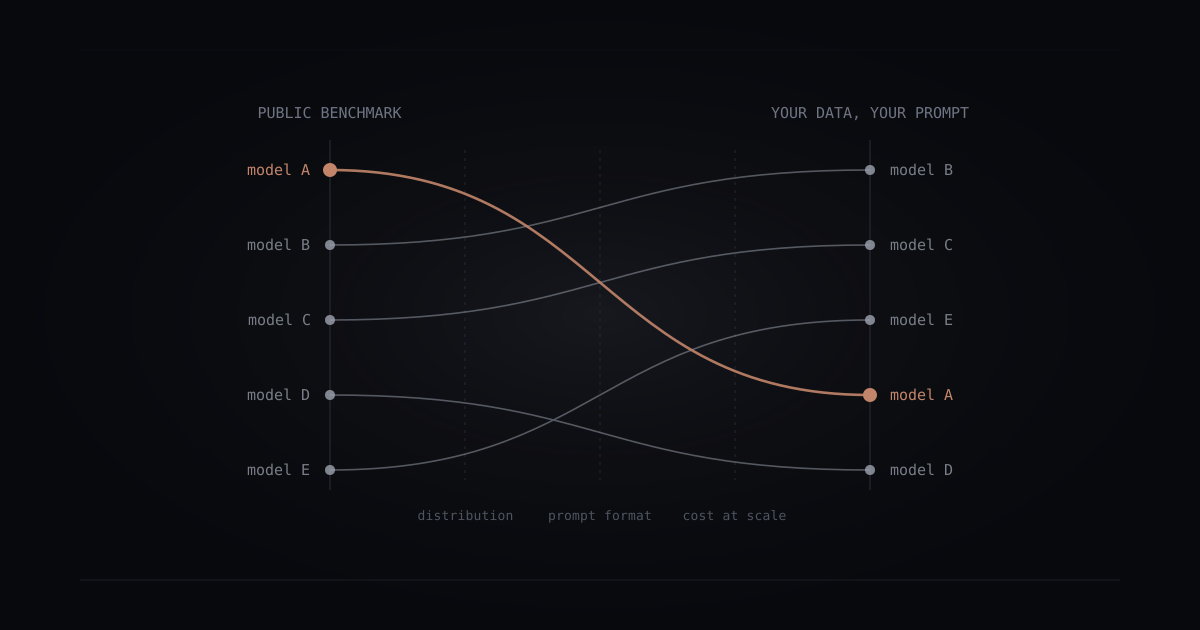
Evaluating LLMs for production: what benchmarks don't tell you
Public benchmarks measure models under controlled conditions. How to build an evaluation on your data and quality criteria that predicts production outcomes.
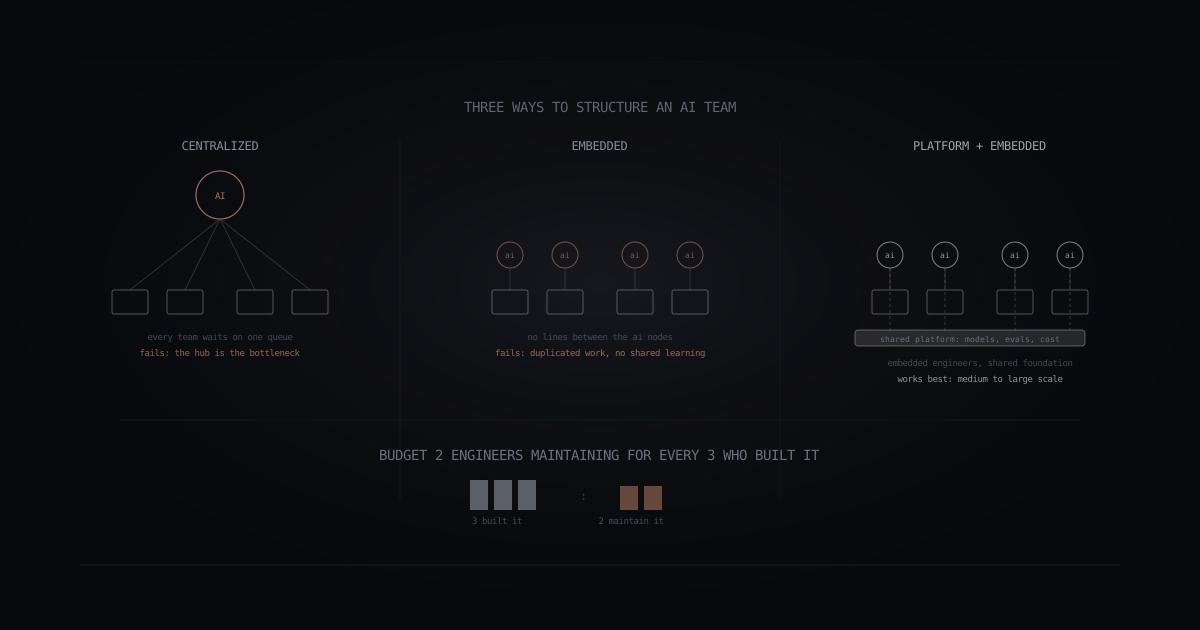
How to structure an AI team
There is no single correct AI team structure, only ones that fit specific contexts and ones that create predictable failure modes. How to tell the difference.
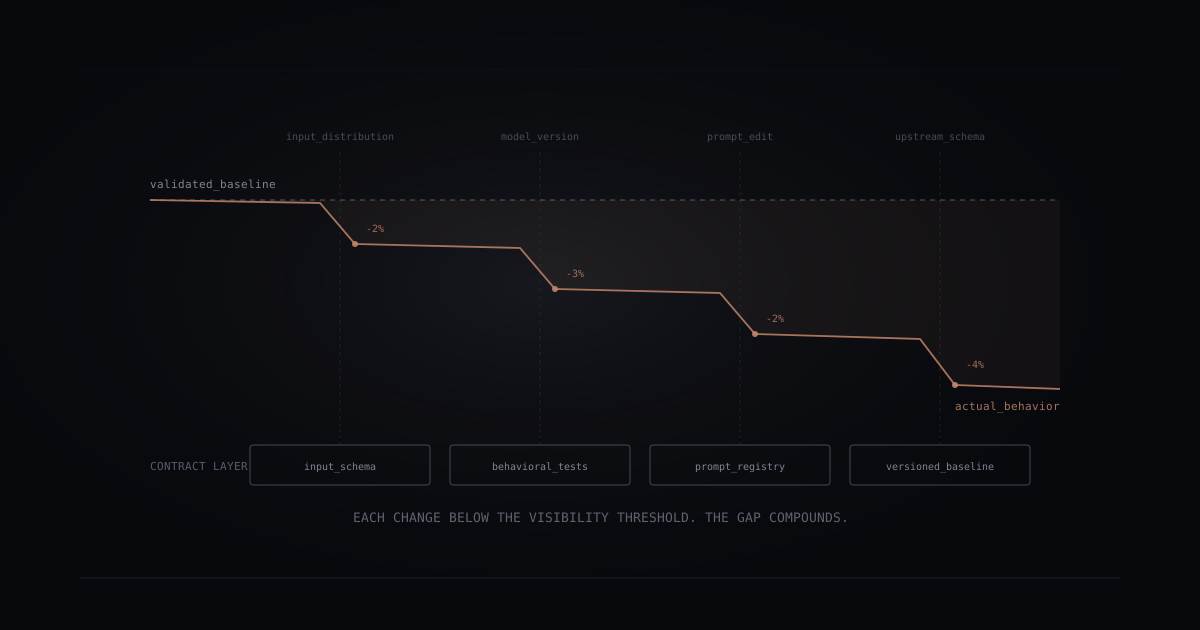
Why AI systems drift without contracts
AI systems rarely fail loudly. They drift because the assumptions behind inputs, outputs, and behavior are never made explicit enough to enforce.
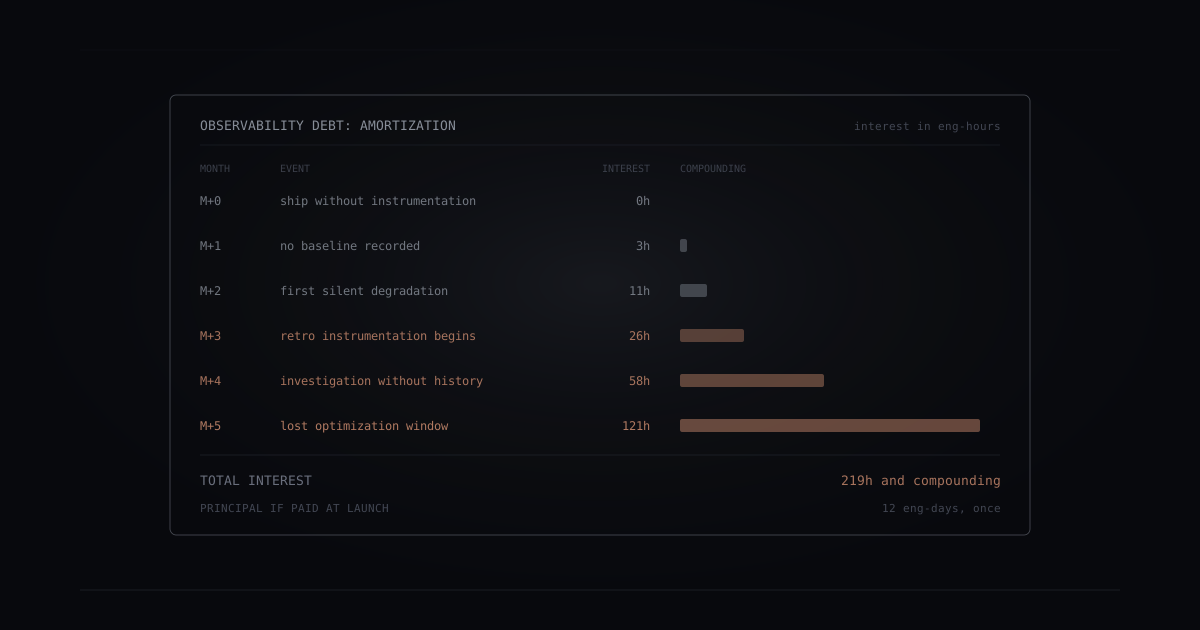
The observability debt in AI systems
AI observability debt compounds faster than technical debt. Failures are probabilistic and latent, and retrofitting costs more than building it early.
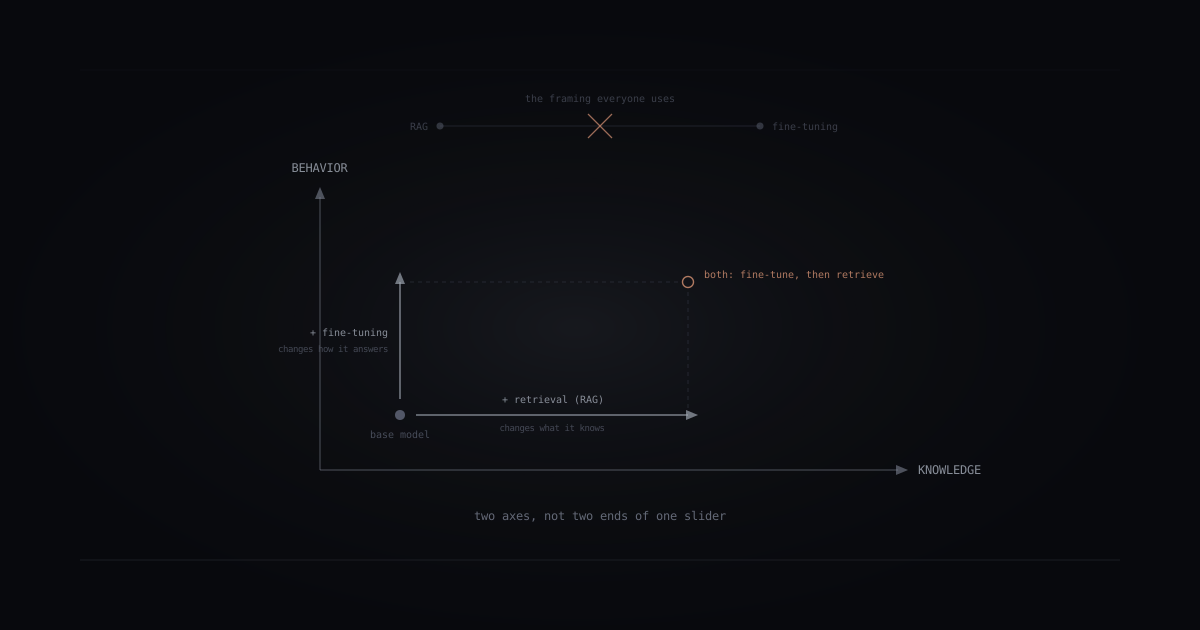
RAG vs fine-tuning: why the comparison mostly doesn't make sense
RAG and fine-tuning solve different problems: knowledge boundaries versus behavior. Treating them as interchangeable wastes months of engineering.
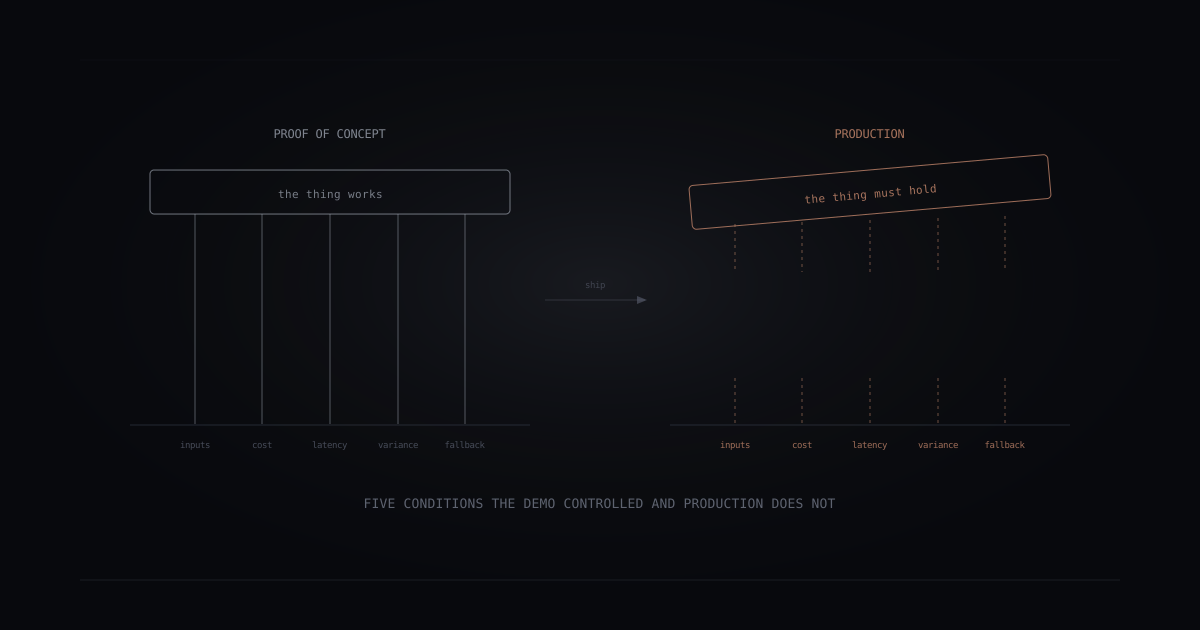
Why your AI proof of concept works but your product doesn't
AI proofs of concept work under curated conditions: controlled inputs, invisible costs, no latency limits. Production removes every one of them.
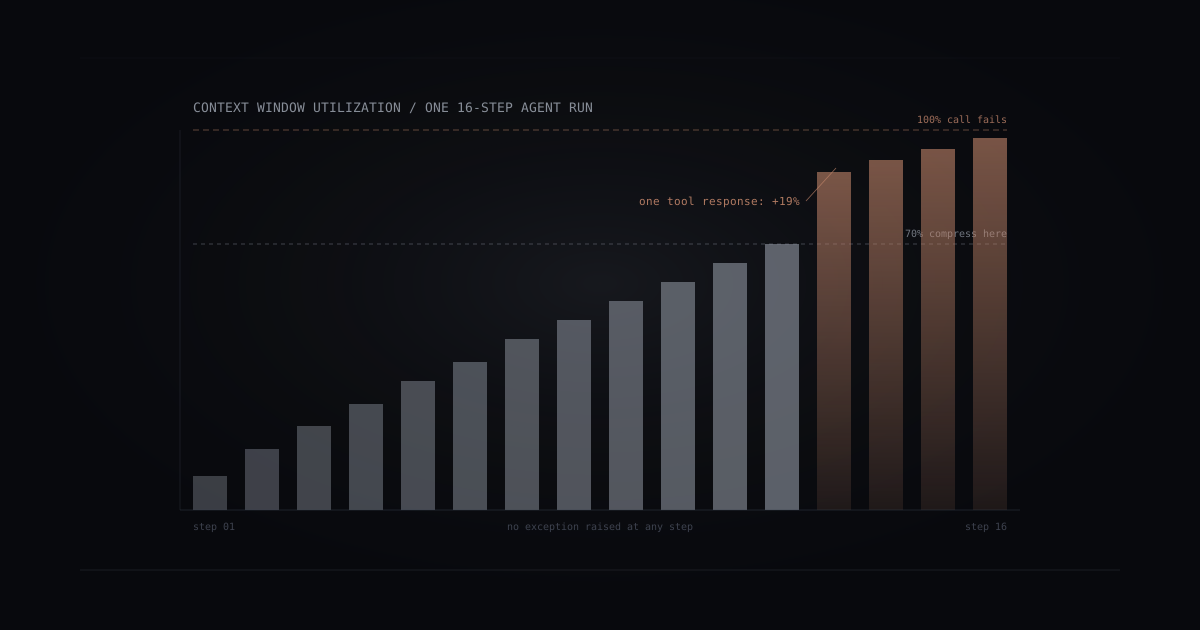
The token budget problem: why your production agents run out of room
Context windows are finite. Production workloads are not. Here is what actually breaks when an agent exhausts its budget, and three patterns that prevent it.
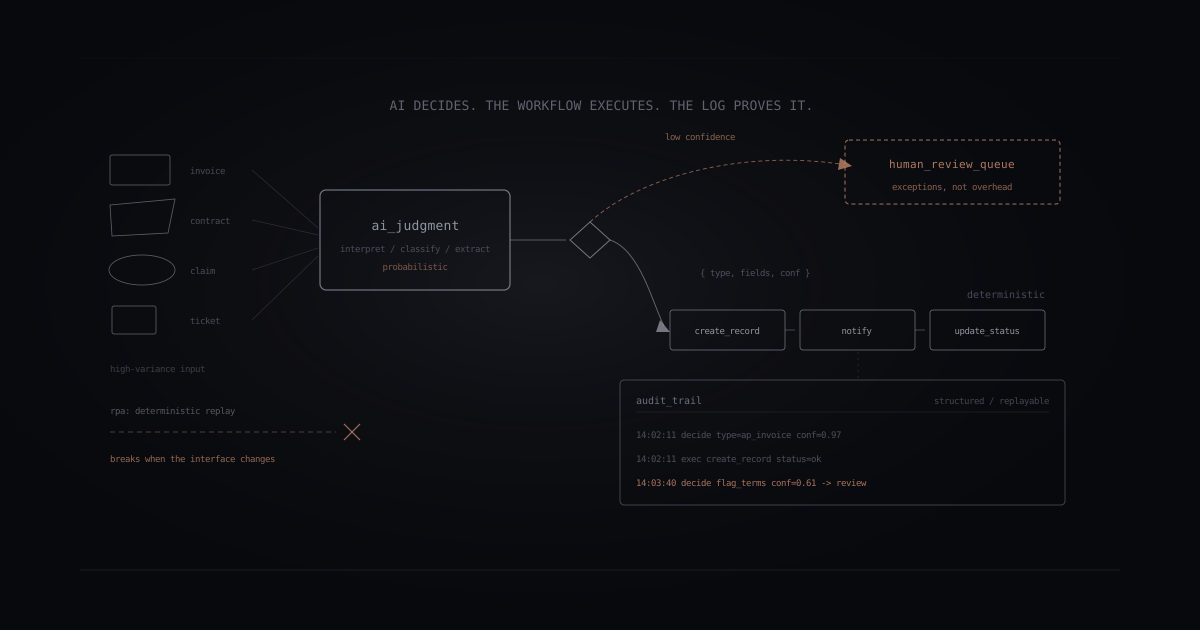
AI workflow automation vs RPA: what actually changes
RPA replays clicks; AI automation makes judgment calls. The hybrid pattern that actually ships pairs AI decisions with structured, auditable execution.
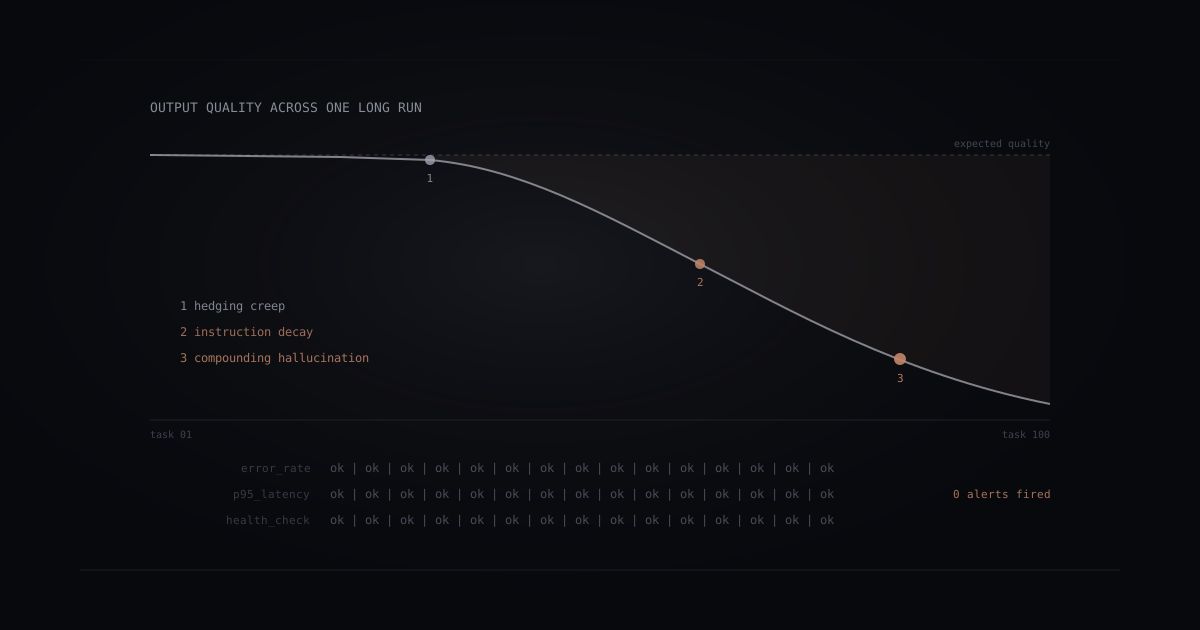
Why long-running AI agents fail silently
Long-running AI agents degrade silently: no errors, only drifting outputs. Here is how context pressure builds and how to catch it early.
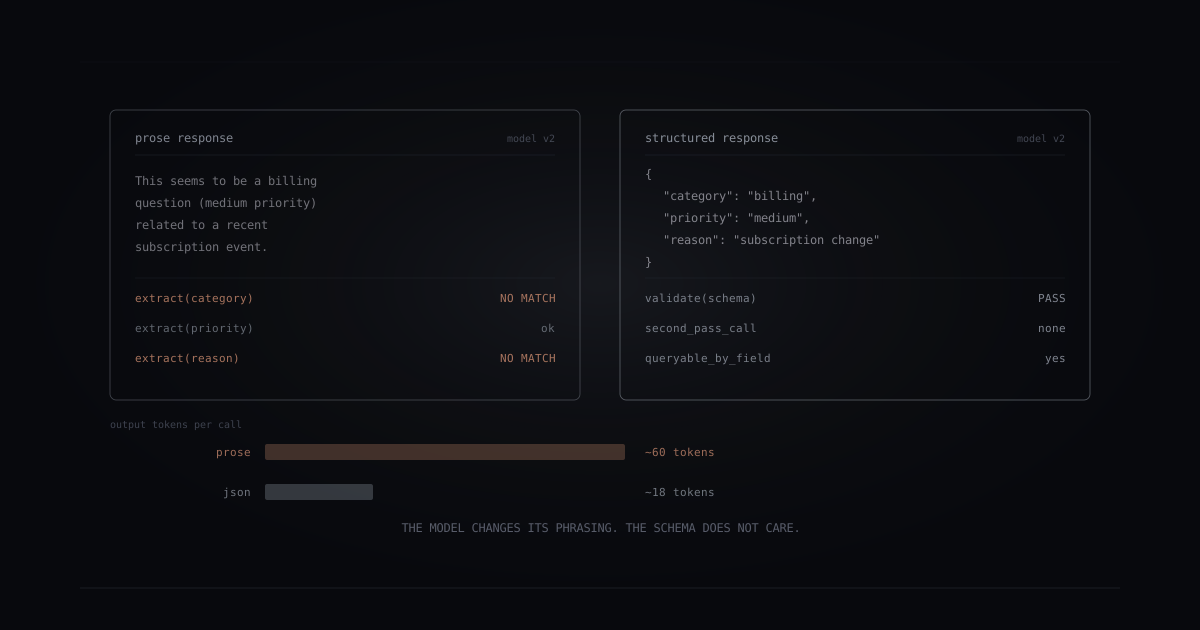
The case for structured outputs in production AI
Most production AI systems parse prose from LLMs instead of requesting structured JSON, and the cost and reliability gap this creates is larger than expected.